Services
Penetration testing of chatbots and LLM agents
Black-box and grey-box penetration testing for LLM-based chatbots and AI agents. These tests uncover attack classes that exist only in agentic AI systems and determine how far an attacker can manipulate your agent's behavior, data access, and system actions through conversation alone.
Unlike traditional security testing, attacks on LLM agents are probabilistic. The same prompt can succeed in 80% of attempts and fail in the remaining 20%, which means a single test result tells you nothing about real risk. The consequences range from unauthorized data access and cross-user PII leakage to agents making financial commitments with no record in your systems.

METHODOLOGY
Engagement phases:
Phase 1: Threat Analysis – we map threat actors and key assets to create a prioritized risk list.
Phase 2: Prep & Recon – we define the scope, rules, and baselines to ready the testing environment.
Phase 3: Core Testing – we run adaptive, multi-layered security tests to log all potential vulnerabilities.
Phase 4: Evaluation & Selection – we triage and validate findings to eliminate false positives and score severity.
Phase 5: Reporting – we deliver a reproducible final report with clear, actionable remediation steps.
Attack surfaces:
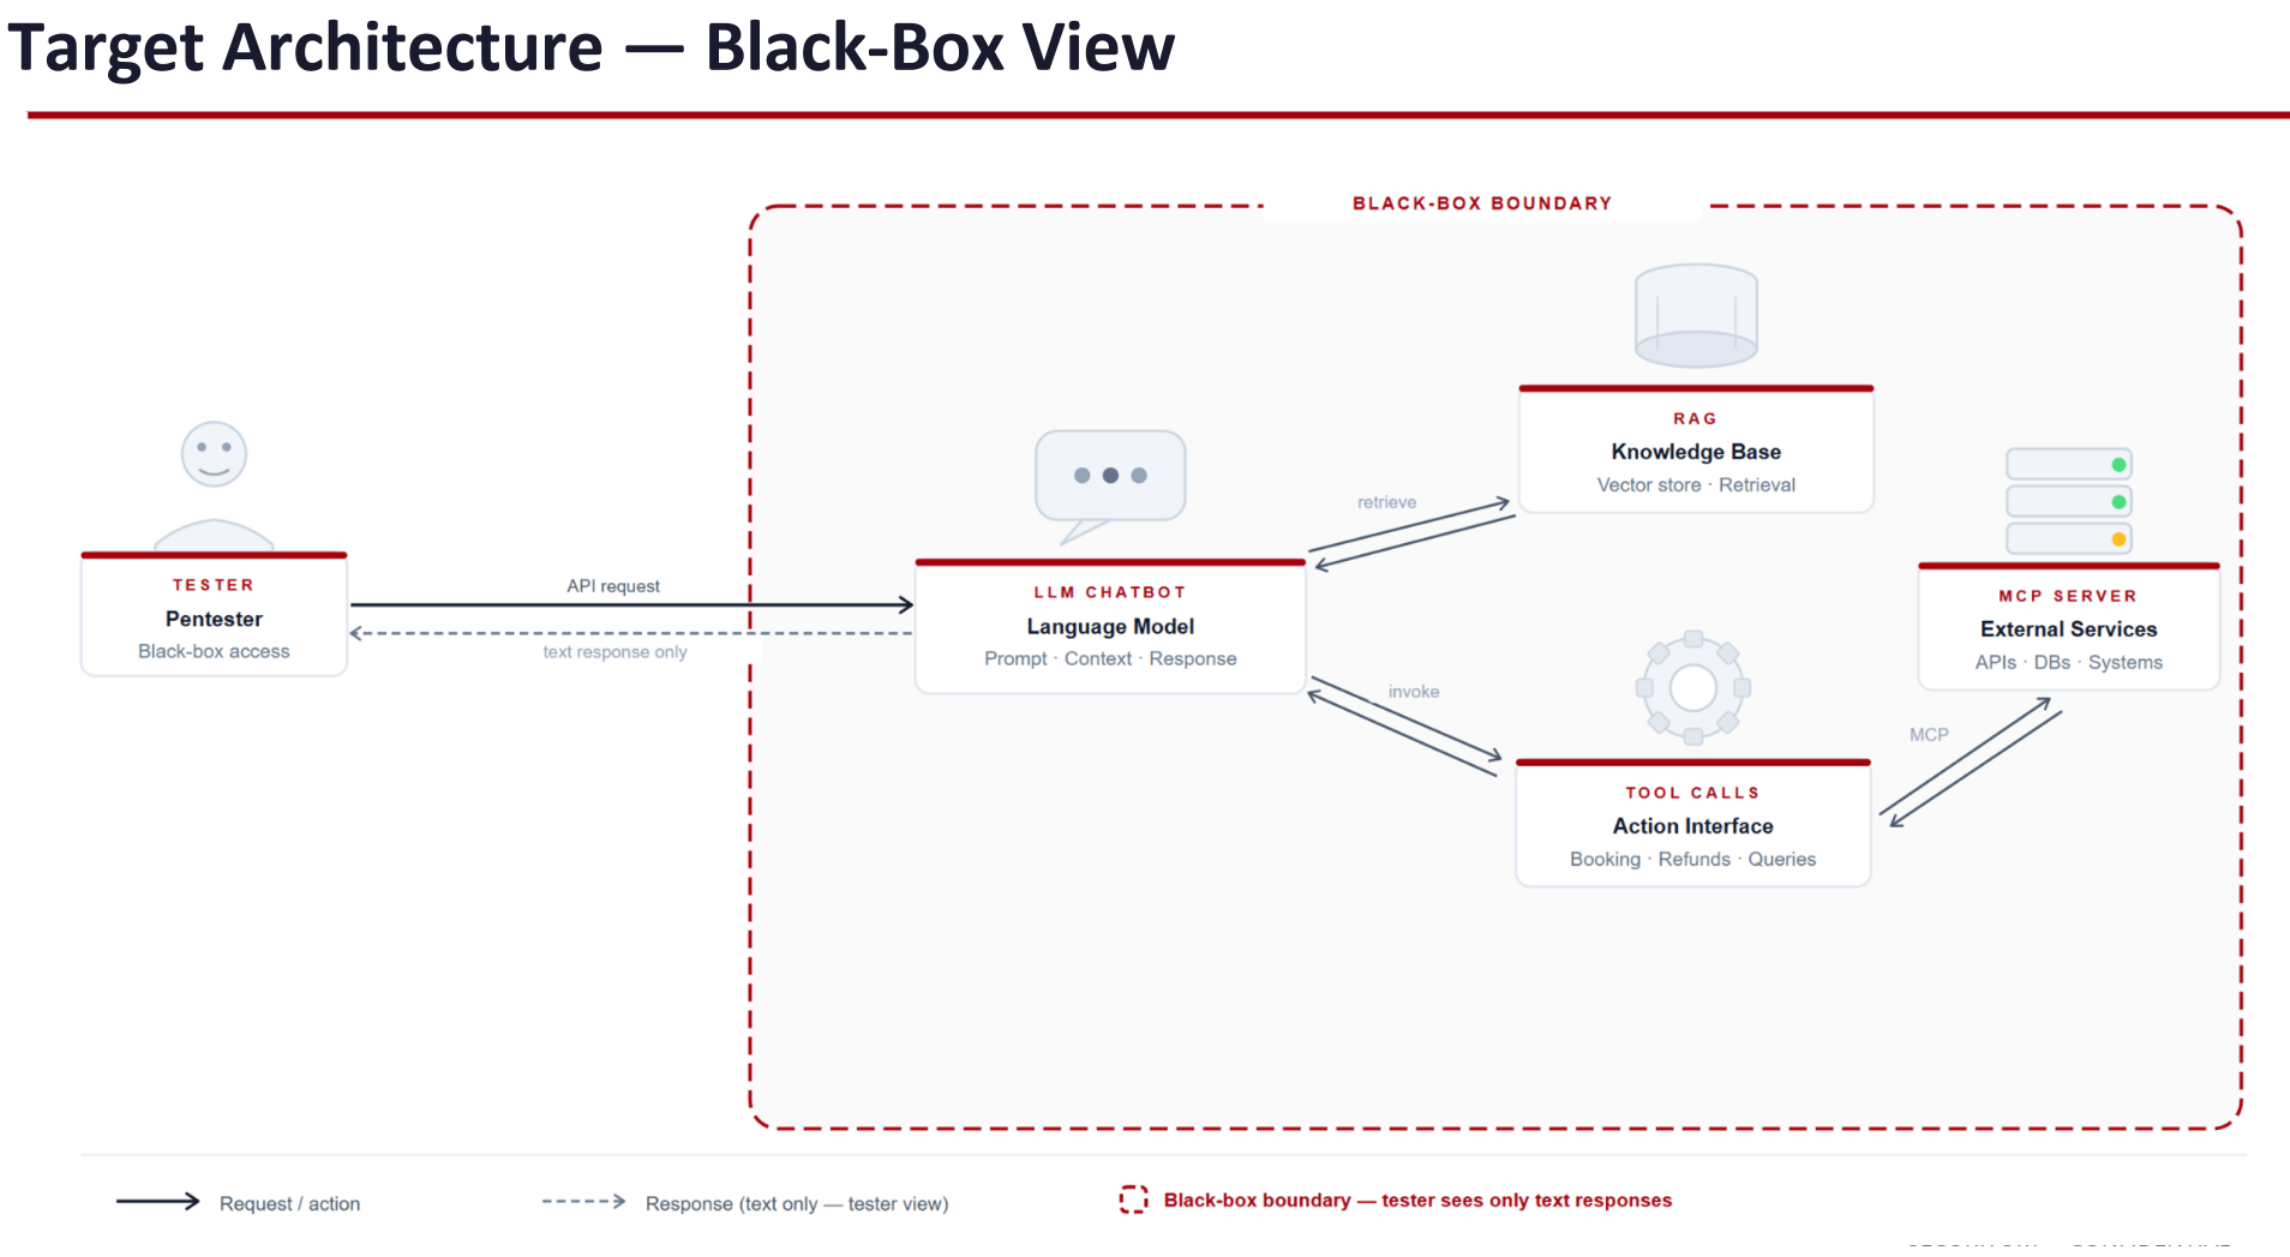
L1: conversational interface -prompt injection, jailbreaks, multi-turn escalation.
L2: RAG knowledge base - indirect injection, context poisoning, retrieval manipulation.
L3: tool calls - phantom actions, confused deputy, privilege escalation.
L4: MCP integrations - tool description injection, cross-session scope violations.
Evaluation:
LLM-Jury: Non-determinism handler - resolves ambiguous LLM outputs into binary verdict. Five local models, air-gapped, majority vote, no external API access.
Oracle: Ground-truth system state - the only source of truth that cannot be manipulated by the LLM. Used for verification after each attack attempt.
Deterministic signals: Pattern-based detection - rule-driven checks that do not require LLM interpretation. Response timing, structural changes, sentinel token hits.
Tooling: Including PyRIT for multi-turn attack campaigns, Garak for initial vulnerability scanning and DeepEval for RAG quality and hallucination detection.
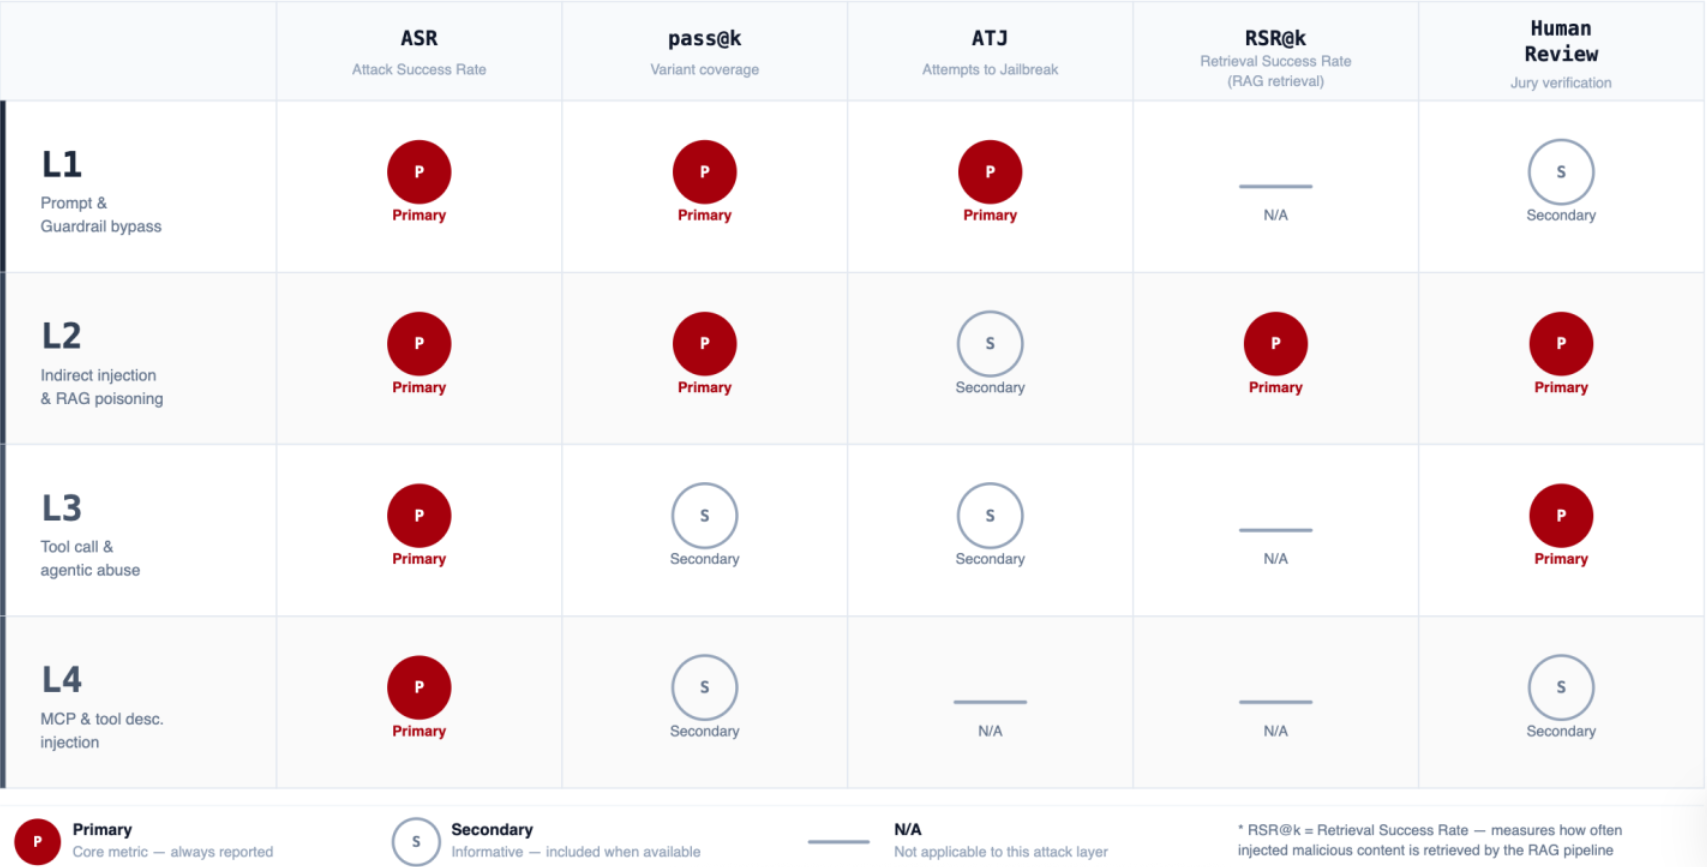
Metrics: ASR (Attack Success Rate), pass@k, ATJ (Attempts to Jailbreak), RSR@k (Retrieval Success Rate).
Severity scored with OWASP AIVSS. Every finding ships with run_id, seed, and full session transcript.
WHAT YOU RECEIVE
• Full non-deterministic security report
• Raw metrics export in CSV/JSON format.
• Free retest possibility within 6 months from report date.
FAQ
Q:
What types of AI can you test?
We test agentic LLM chatbots.
Q:
Do you need source code access?
We do not. These tests are conducted in blackbox or greybox model, meaning we engage without any information or with partial information.
Q:
Will my data be processed by any other companies during testing?
It will not. Securitum has air-gapped internal infrastructure set, which means your data is safe and not used to train any models.
Q:
How long does the engagement take?
Depending on the type of infrastructure you run. Typically the test takes around 10 man-days.
Q:
What do we receive in the report?
Reports feature AIVSS scoring, comprehensive PoCs complete with run_id and seed, alongside raw data in CSV/JSON formats.
Q:
What OWASP standards do you cover?
We address most of the OWASP LLM Top 10 and Agentic AI Security guidelines, with the exact scope of coverage depending on the agreed parameters.
Q:
Can we retest after fixing the findings?
Yes, we provide retest of found vulnerabilities free of charge within 6 months from receiving end report.